
 我要评论
mysql按天分组统计查询每天数据量
需求中经常会有按日期,月份,年份分组统计的操作
groupby直接是实现不了的
需要转化一下,话不多说,看代码
select
	from_unixtime(create_time, '%y-%m-%d') as day, create_time,
	count( distinct uid ) as amount
from
	`black_production_user`
where
	create_time >= 1588262400
	and create_time <= 1607529599
	group by day
以上代码可以按每天分组并统计每天的新增数据量,按月或年的只要修改日期格式就好
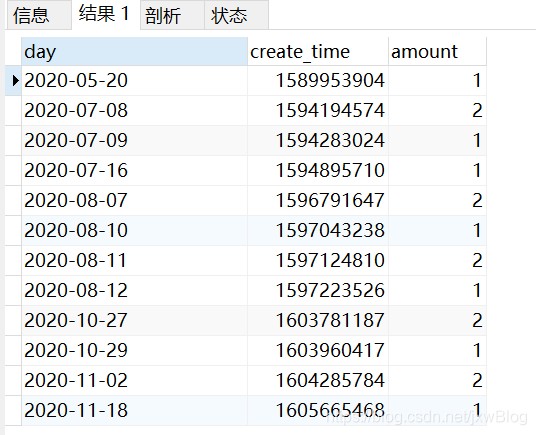
但上面只统计到了有数据的天数,某天没有时就不返回该天,实际情况中某天没有希望返回0
那按上面的结果在程序中循环赋默认值也可以
其实sql也可以实现
具体看下面代码:
select day,sum(count) as add_num from (
select count(distinct uid) count, from_unixtime(create_time,'%y-%m-%d') day from `black_production_user` a
where a.create_time >= 1588262400 and a.create_time < 1607529599
group by day
union all
select @uu:=0 as count,day from (
select @num:=@num+1 as number,date_format(adddate('2020-05-01 00:00:00', interval @num day),'%y-%m-%d') as day
from `black_production_user` a ,(select @num:=-1) t
order by day ) rr
) sss group by sss.day order by day
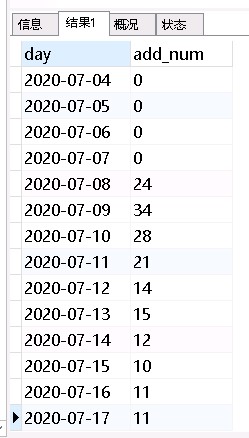
这条sql稍微有点绕,需要自己理解便可,查询结果如下,某天没有数据默认有 0 填充
注意:
from_unixtime 针对于数据时间存储格式为时间戳,若库中时间存储的日期格式 :
如 : 2020-12-10 10:03:24,这样的使用 date_format 即可
总结
以上为个人经验,希望能给大家一个参考,也希望大家多多支持代码网。





发表评论