
 我要评论
摘要
本文介绍了如何利用 paddleocr 实现对 pdf 文件或图片 的文字识别,并在识别后将文本内容按照 原始版面位置 进行还原重建。文章详细讲解了实现流程,包括 图像预处理、ocr 识别、版面坐标提取与重排、以及最终生成 可编辑的 pdf 或可视化输出 的过程。
本文将带你使用 paddleocr 实现一个完整流程:
# 升级 pip
python -m pip install --upgrade pip

# 设置清华源加速下载(可选)
pip config set global.index-url https://pypi.tuna.tsinghua.edu.cn/simple

# 安装 paddlepaddle cpu 版本
python -m pip install paddlepaddle==3.2.0 -i https://www.paddlepaddle.org.cn/packages/stable/cpu/

# 安装辅助库
python -m pip install pymupdf pillow reportlab tqdm beautifulsoup4

# 安装指定版本 paddleocr
python -m pip install paddleocr==3.2.0
1. 初始化 paddleocr(使用高精度服务器模型)
import os
import cv2
import json
import numpy as np
import base64
from xml.etree.elementtree import element, subelement, tostring
from paddleocr import paddleocr
ocr = paddleocr(
    text_detection_model_name="pp-ocrv5_server_det",
    text_recognition_model_name="pp-ocrv5_server_rec",
    use_doc_orientation_classify=false,
    use_doc_unwarping=false,
    use_textline_orientation=false
)
2. 执行 ocr 识别
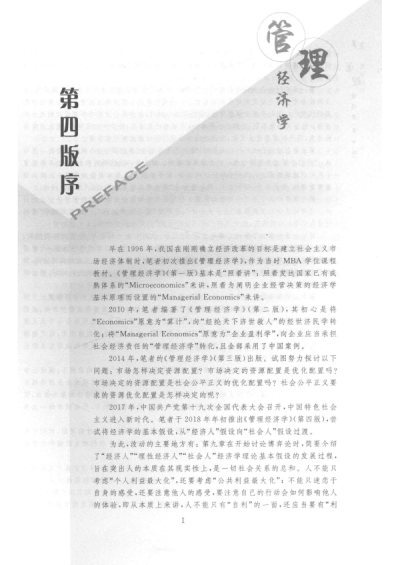
input_img = "./page_4.png"
result = ocr.predict(input_img)
data = result[0]  # 取第一页结果
返回结构包含:
- rec_texts: 识别的文本列表
- rec_polys: 每个文本的多边形坐标(4个点)
- input_path: 原图路径
3. 读取原图获取尺寸
orig_img = cv2.imread(data["input_path"])
img_h, img_w = orig_img.shape[:2]
print(f"原图尺寸: {img_w} x {img_h}")
4. 创建 svg 根节点(透明背景)
svg = element("svg", {
    "xmlns": "http://www.w3.org/2000/svg",
    "width": str(img_w),
    "height": str(img_h),
    "viewbox": f"0 0 {img_w} {img_h}",
    "style": "background:none"
})
5. 内嵌仿宋字体(base64 编码)
font_path = os.path.expanduser("~/.paddlex/fonts/simfang.ttf")

with open(font_path, "rb") as f:
    font_data = base64.b64encode(f.read()).decode("utf-8")

style_el = subelement(svg, "style")
style_el.text = f"""
@font-face {{
  font-family: 'simfang';
  src: url(data:font/truetype;charset=utf-8;base64,{font_data}) format('truetype');
}}
text {{
  font-family: 'simfang';
  fill: rgb(0,0,0);
  dominant-baseline: middle;
  text-anchor: middle;
  white-space: pre;
}}
6. 智能绘制文字(支持旋转 + 竖排)
for text, poly in zip(data["rec_texts"], data["rec_polys"]):
    if not text.strip():
        continue

    box = np.array(poly, dtype=np.float32).reshape(4, 2)
    x0, y0 = box.min(axis=0)
    x1, y1 = box.max(axis=0)
    w_box, h_box = x1 - x0, y1 - y0

    # 计算旋转角度(以左下→右下边为基准)
    angle = np.degrees(np.arctan2(box[1][1] - box[0][1], box[1][0] - box[0][0]))
    font_size = max(8, int(min(w_box, h_box) * 0.8))

    # 判断是否为竖排文字
    vertical = h_box > 2.5 * w_box and h_box > 60

    if vertical:
        # 竖排:逐字垂直排列
        cx = (x0 + x1) / 2
        y = y0
        gap = h_box / max(len(text), 1)
        for ch in text:
            text_el = subelement(svg, "text", {
                "x": str(cx),
                "y": str(y + gap / 2),
                "font-size": str(font_size),
                "transform": f"rotate({angle},{cx},{y + gap / 2})"
            })
            text_el.text = ch
            y += gap
    else:
        # 横排:整体旋转
        cx = (x0 + x1) / 2
        cy = (y0 + y1) / 2
        text_el = subelement(svg, "text", {
            "x": str(cx),
            "y": str(cy),
            "font-size": str(font_size),
            "transform": f"rotate({angle},{cx},{cy})"
        })
        text_el.text = text
7. 保存 svg 文件
output_svg = "page_1_transparent.svg"
with open(output_svg, "wb") as f:
    f.write(tostring(svg, encoding="utf-8", xml_declaration=true))

print(f"已生成透明可复制文字 svg: {output_svg}")
8.效果展示

9.完整代码
import os
import cv2
import json
import numpy as np
import base64
from xml.etree.elementtree import element, subelement, tostring
from paddleocr import paddleocr
# ================== 配置 ==================
ocr = paddleocr(
    text_detection_model_name="pp-ocrv5_server_det",
    text_recognition_model_name="pp-ocrv5_server_rec",
    use_doc_orientation_classify=false,
    use_doc_unwarping=false,
    use_textline_orientation=false
)

input_img   = "./page_4.png"
output_pdf  = "page_1_restored.pdf"
input_json = "./page_4_res.json"
font_path   = os.path.expanduser("~/.paddlex/fonts/simfang.ttf")
scale       = 3


# ================== 1. ocr 使用 predict ==================
print("正在执行 ocr: result = ocr.predict(input_img)")
try:
    results = ocr.predict(input_img)
except exception as e:
    print(f"\nocr 失败页: {e}")
    continue

# ---------- 保存 json + 带框图 ----------
for res_idx, res in enumerate(results):
    res.save_to_img(os.path.join(f"page_boxed.png"))
    res.save_to_json(input_json)

# ================== 配置 ==================
font_path  = os.path.expanduser("~/.paddlex/fonts/simfang.ttf")
output_svg = "page_1_transparent.svg"
text_color = (0, 0, 0)  # 黑色文字
if not os.path.exists(font_path):
    raise filenotfounderror(f"字体未找到: {font_path}")

# ================== 1. 加载 ocr json ==================
if not os.path.exists(input_json):
    raise filenotfounderror(f"ocr 结果未找到: {input_json}")
with open(input_json, "r", encoding="utf-8") as f:
     data = json.load(f)

texts = data["rec_texts"]
polys = data["rec_polys"]

input_path = data.get("input_path")
if not input_path or not os.path.exists(input_path):
    raise filenotfounderror(f"原图未找到: {input_path}")

# ================== 2. 获取原图尺寸 ==================
orig_img = cv2.imread(input_path)
if orig_img is none:
    raise valueerror(f"无法读取原图: {input_path}")
img_h, img_w = orig_img.shape[:2]
print(f"原图尺寸: {img_w} x {img_h}")

# ================== 3. 创建 svg 根节点 ==================
svg = element("svg", {
    "xmlns": "http://www.w3.org/2000/svg",
    "width": str(img_w),
    "height": str(img_h),
    "viewbox": f"0 0 {img_w} {img_h}",
    "style": "background:none"
})

# ================== 4. 内嵌字体(simfang) ==================
if not os.path.exists(font_path):
    raise filenotfounderror(f"字体未找到: {font_path}")

with open(font_path, "rb") as f:
    font_data = base64.b64encode(f.read()).decode("utf-8")

style_el = subelement(svg, "style")
style_el.text = f"""
@font-face {{
  font-family: 'simfang';
  src: url(data:font/truetype;charset=utf-8;base64,{font_data}) format('truetype');
}}
text {{
  font-family: 'simfang';
  fill: rgb({text_color[0]}, {text_color[1]}, {text_color[2]});
  dominant-baseline: middle;
  text-anchor: middle;
  white-space: pre;
}}
"""

# ================== 5. 绘制文字(透明背景) ==================
for text, poly in zip(texts, polys):
    if not text.strip():
        continue

    box = np.array(poly, dtype=np.float32).reshape(4, 2)
    x0, y0 = box.min(axis=0)
    x1, y1 = box.max(axis=0)
    w_box, h_box = x1 - x0, y1 - y0
    angle = np.degrees(np.arctan2(box[1][1] - box[0][1], box[1][0] - box[0][0]))
    font_size = max(8, int(min(w_box, h_box) * 0.8))

    vertical = h_box > 2.5 * w_box and h_box > 60

    if vertical:
        # 竖排文字
        cx = (x0 + x1) / 2
        y = y0
        gap = h_box / max(len(text), 1)
        for ch in text:
            text_el = subelement(svg, "text", {
                "x": str(cx),
                "y": str(y + gap / 2),
                "font-size": str(font_size),
                "transform": f"rotate({angle},{cx},{y + gap / 2})"
            })
            text_el.text = ch
            y += gap
    else:
        # 横排文字
        cx = (x0 + x1) / 2
        cy = (y0 + y1) / 2
        text_el = subelement(svg, "text", {
            "x": str(cx),
            "y": str(cy),
            "font-size": str(font_size),
            "transform": f"rotate({angle},{cx},{cy})"
        })
        text_el.text = text

# ================== 6. 保存透明可复制 svg ==================
with open(output_svg, "wb") as f:
    f.write(tostring(svg, encoding="utf-8", xml_declaration=true))

print(f"已生成透明可复制文字 svg: {output_svg}")
以上就是python使用paddleocr实现pdf/图片文字识别与版面还原的详细内容,更多关于python paddleocr文字识别的资料请关注代码网其它相关文章!


发表评论